Cloudflare Flue and the Three-Layer Agent Stack
Flue matters less as a framework than as a signal. The agent stack is splitting into layers the way web stacks did twenty years ago, and the bottom layer, the runtime that keeps an agent alive, recovers it when it dies, and contains it when it runs code you did not write, is becoming a platform decision on the scale of choosing a cloud. You can change a framework in a sprint. You do not change a runtime in a sprint.
One disclosure before anything else, because it changes how you should read this. We build agents for clients on whichever platform fits the problem, we are not a Cloudflare partner, and nobody is paying for this assessment. What follows is a read on a category, using one vendor's announcement as the occasion, and the parts I am least sure about are marked as questions rather than smoothed over.
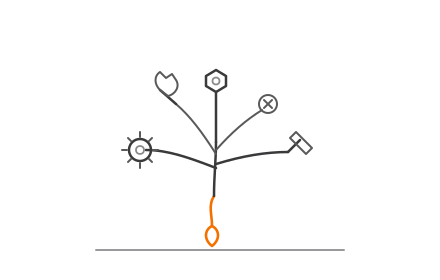
- Top floor Framework: developer experience
- Middle floor Harness: the agentic loop
- Ground floor Runtime: durability, state, secure execution
What did Cloudflare announce with Flue?
On 17 June 2026, Cloudflare announced Flue, an agent framework, and made a larger change underneath it. Per that post, Flue shipped as a 1.0 beta built on the Pi harness, the same harness OpenClaw is built on, and what Cloudflare says distinguishes it is the declarative approach: "you don't script what your agent does, you describe what it knows." Alongside it, the Agents SDK became, in Cloudflare's words, a runtime any agent framework can build on, rather than something supporting only Cloudflare's own first-party harness, Project Think. Cloudflare also said it was rolling out agents in the dashboard.
The framing Cloudflare put around all of this is the interesting part for a buyer. Its claim, as of that June post, is that "2026 is the year agent harnesses go to production," and that teams are now deploying agents as load-bearing infrastructure rather than prototypes.
The follow-on came at Agents Week. Cloudflare's review of that week, dated 10 August 2026, covers tracing, replay, and human-in-the-loop approvals, with the detailed observability announcement published on 4 August. Cloudflare's Agents documentation, checked on 20 September 2026, states that agent tracing "helps you understand what an agent did at every turn, including its model calls, tool runs, and approval requests", that span attributes follow the OpenTelemetry generative AI semantic conventions, that Think and Flue v2 and later instrument agents automatically, and that "Tracing is free while in beta." It also states that "Beginning October 1, 2026, tracing will be included in existing Workers Observability pricing."
Every fact in this section is Cloudflare's own, from Cloudflare's pages, on the dates given. I have not run any of it in production, and this post contains no benchmarks because I have none to offer.
What are the three layers of a production agent?
The most useful thing in the June post is not Flue. It is the vocabulary. Cloudflare splits a production agent into three layers, and once you have that split, a lot of vendor noise sorts itself out.
The framework is, per Cloudflare, "the project structure, the conventions, the integrations, the CLI and the developer experience for building agents." The harness is "the agentic loop that calls tools, reads results, manages context and keeps going." The runtime is "the compute, state, and storage primitives everything above depends on."
| Layer | Its job | The business question it answers | Where it comes from |
|---|---|---|---|
| Framework | Project structure, conventions, CLI, developer experience | How fast can our team build and change an agent? | Usually adopted, and comparatively cheap to swap |
| Harness | The agentic loop: calling tools, reading results, managing context | Does the agent make good decisions, and can we see why? | Adopted or built, and the layer we argue about most |
| Runtime | Durable execution, state, storage, secure execution of untrusted code | Who keeps this alive at 3am, and what happens when it dies? | Bought from a platform, and the hardest to replace |
If you read one row, read the last. The harness is where the interesting engineering conversation lives, which is why it gets the attention, and we wrote about that layer in detail in the agent harness pattern. The runtime is where the money and the commitment live. It is also the layer most teams choose by accident, because it arrives bundled with whatever they tried first. If you are still assembling the wider picture of how AI features get built and maintained, what an AI factory is is the broader frame this sits inside.
What breaks in production, and which layer fixes it?
Cloudflare's own list of hard problems is a good inventory, and it is worth noting that none of them are about model quality. Per the June post, the questions are distributed-systems questions: when an agent is interrupted, how does it resume gracefully without losing context or wasting tokens, and how do you securely run code the model wrote.
Four failures show up again and again, and three of them land on the same floor.
Interruption. An agent is a long-running process in a world of short-running requests. It gets interrupted, and the question is whether it resumes where it left off or starts again. Starting again is not just slow, it is expensive, because every token it already spent is spent twice. Runtime.
Untrusted code. A capable agent writes code and wants to run it. That code is untrusted by definition, including when your own model wrote it. Somebody has to contain it. Runtime.
State. An agent that forgets between turns is a chatbot. Memory, history, and the record of what it already did have to live somewhere durable. Runtime.
Observability. The failure mode that catches teams out is not the crash, it is the agent that returns HTTP 200 while quietly doing the wrong thing for a week. You cannot detect that from uptime. You need per-turn visibility into what it decided, which tools it called, and what it spent, which is precisely what Cloudflare's tracing describes capturing. This one cuts across all three layers.
What does this change about cost?
It splits one number into three, and the three behave differently.
- Model tokens. Scales with how much the agent thinks and how often
- Runtime and state. Scales with how long agents live and what they keep
- Observability. Scales with how much you watch, and how long you keep it (Paid from 1 Oct 2026, per Cloudflare)
Model tokens are the line everyone already watches, and they scale with how much the agent thinks. Runtime and state scale with something else entirely: how long agents stay alive and how much they remember. An agent that sleeps for six hours waiting on an approval costs nothing in tokens and something in durable state. Observability scales with how closely you watch and how long you keep what you saw.
The third line is the one I would put in front of a finance team this quarter, because it is about to change shape. Cloudflare's docs state that agent tracing is free while in beta and that from 1 October 2026 it moves into existing Workers Observability pricing, with each span counted as an observability event. Set aside whether that is cheap, which depends entirely on your volumes. The structural point is that watching your agents is becoming a metered line item rather than a free extra, and an agent that emits a span per turn, per tool call, and per approval emits a lot of spans. Budget for observability as a real cost, not a rounding error, and decide deliberately how long you retain traces.
That is a category observation, not a complaint about Cloudflare's pricing. Every platform is heading to the same place, because storing and indexing this much telemetry genuinely costs money.
How locked in are you?
Not equally at every layer, which is the useful part.
Cloudflare is explicit that Flue is a multi-cloud framework, and states that on Node.js each agent runs as a long-lived process you can deploy to any VM or container, run in GitHub Actions, or embed on an existing server. Take that as the vendor's description of its own portability, which is a reasonable thing to publish and still a claim to test rather than assume.
The questions I would ask before committing an agent to any runtime, this one included, are simple and rarely answered on a pricing page. What happens to a running agent, its state, and its accumulated history if we leave? Can we export traces and state in a standard format, or only view them in your dashboard? If durable execution is the thing we depend on, what is the documented behaviour when the platform itself has an incident? Cloudflare's use of OpenTelemetry conventions for spans is a genuinely good sign here, because telemetry in a standard shape is telemetry you can take with you. Its docs also note that Workers does not yet support the OpenTelemetry API directly, which is the kind of detail worth tracking rather than assuming away.
What would we do if we were choosing today?
Four things, in this order.
Choose the harness for the task, not the brand. The loop is where behaviour lives. Pick the one whose decisions you can inspect and replay, because that is what you will need on the day something goes wrong.
Choose the runtime for durability and security you can verify. Ask for the failure behaviour in writing. This is the layer you will live with longest, so weigh it like a cloud decision rather than a library choice.
Treat observability as infrastructure, with a budget and a retention policy. Decide now what you keep, for how long, and who looks at it. A trace nobody reads is a cost with no benefit.
Keep evals and governance yours, whatever the platform. This is the one I would not outsource at any layer. Your definition of a correct answer, and your rules about what an agent may do unsupervised, should be portable across every vendor in this post. Our guides on evaluating LLM outputs and writing an AI governance policy are both platform-neutral on purpose, and that is the point.
Where this leaves you
The honest summary is that agents have stopped being a model problem and become an infrastructure problem, and infrastructure problems are decided by who is accountable at 3am rather than by which demo was most impressive. Flue is worth a look if you are building on Cloudflare already. The three-layer split is worth borrowing whatever you build on.
If you are working out which layers to own and which to buy, Codiot's AI agents team does this work across platforms, and our AI development practice covers the evaluation and data plumbing that has to hold regardless of whose runtime you pick.